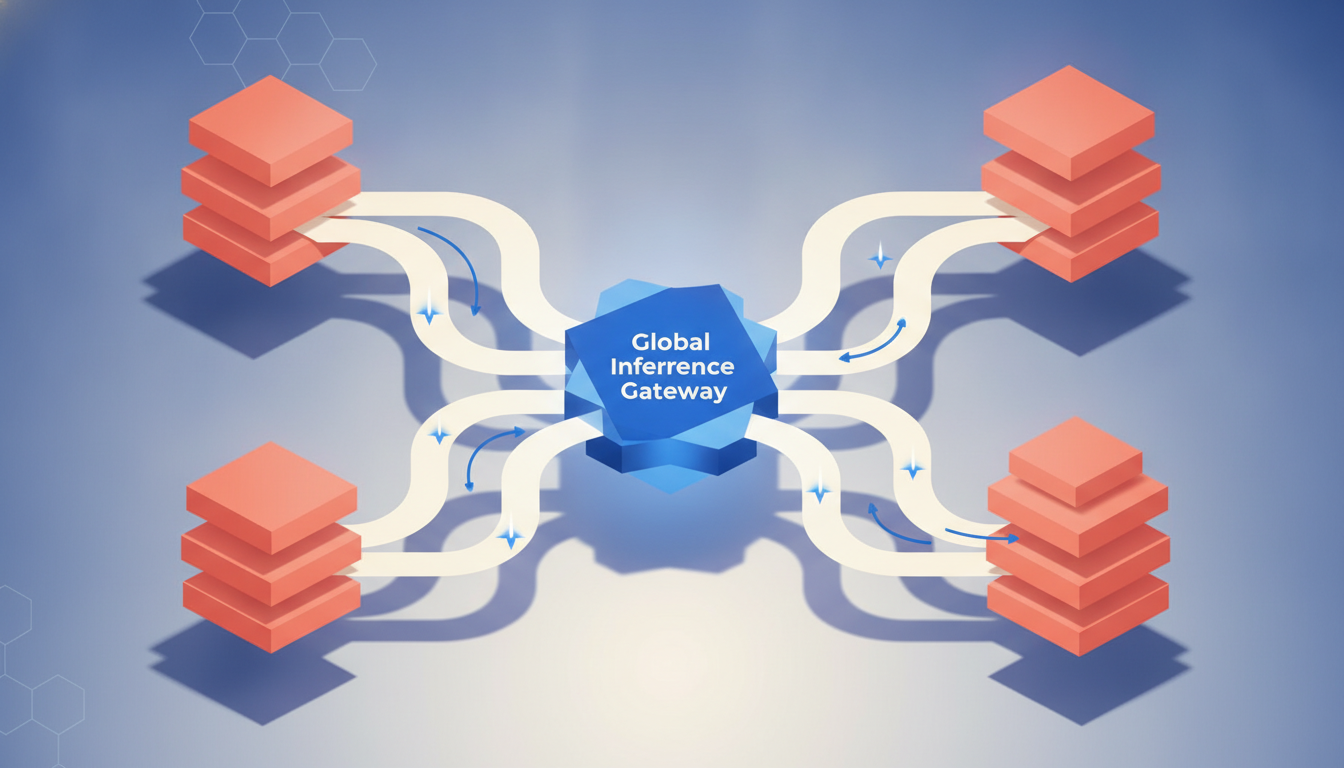
Amazon Web Services has introduced the Global Inference Gateway for Amazon SageMaker HyperPod, allowing organizations to route machine learning inference requests across multiple clusters and AWS regions through a single managed endpoint.
The gateway addresses a capacity utilization problem: during traffic peaks, requests can queue on saturated clusters while GPUs in other clusters or regions sit idle. According to AWS, the new service automatically routes traffic based on real-time signals including key-value cache utilization and queue depth, sending requests to the best-suited cluster across registered regions.
The Global Inference Gateway works as a second tier above the existing Inference Gateway. While the original Inference Gateway routes requests to specific pods within a single cluster, the new global layer selects which cluster receives each request and carries it over the AWS backbone. Inside each cluster, the existing pod-level routing remains unchanged.
AWS says the service provides automatic failover when clusters fail and handles authentication through AWS Signature Version 4 and AWS Identity and Access Management. Organizations running models across multiple clusters previously needed to manage separate endpoints for each cluster, requiring custom load balancers, DNS configuration and cross-region networking.
AWS describes a scenario where a team serving four models across five HyperPod clusters in two regions previously tracked 20 endpoints—one per model per cluster. The Inference Gateway reduced that to five endpoints, one per cluster, but clients still had to select clusters themselves. The Global Inference Gateway consolidates routing to a single entry point.