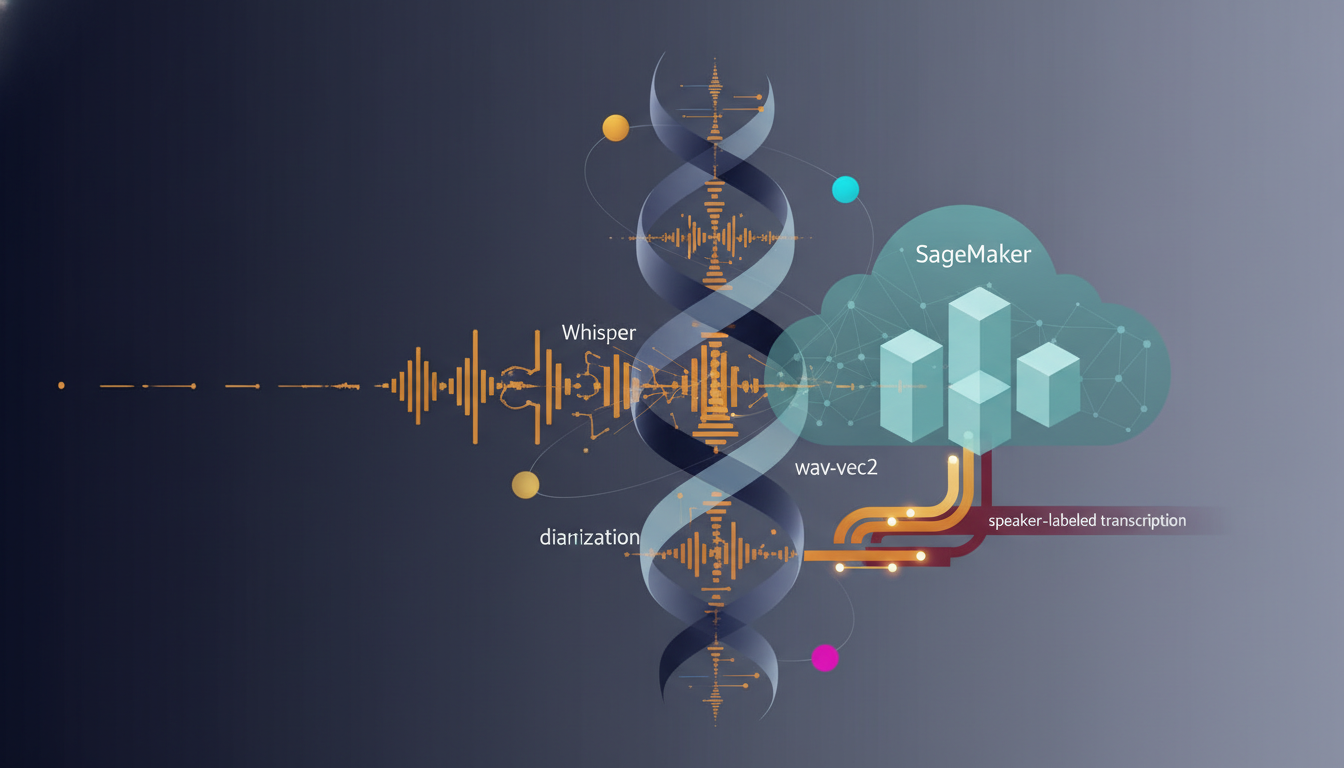
According to Amazon AWS AI, the company has released a WhisperX Deep Learning Container that packages multiple speech processing technologies into a single GPU-ready image. The container combines OpenAI’s Whisper speech recognition model, wav2vec2 forced alignment, and speaker diarization capabilities.
The solution is designed for deployment on Amazon SageMaker AI, supporting both real-time and asynchronous endpoints. According to AWS, the container enables word-level, speaker-labeled transcription, allowing users to identify which speaker said specific words in audio recordings. The announcement indicates that AWS has also addressed production implementation details necessary for deploying the technology in real-world applications.
The WhisperX container represents AWS’s effort to simplify the deployment of advanced speech-to-text capabilities by bundling multiple open-source technologies into a pre-configured, GPU-optimized package. By offering both real-time and asynchronous processing options through SageMaker AI, the solution aims to accommodate different use cases and latency requirements for transcription workloads.